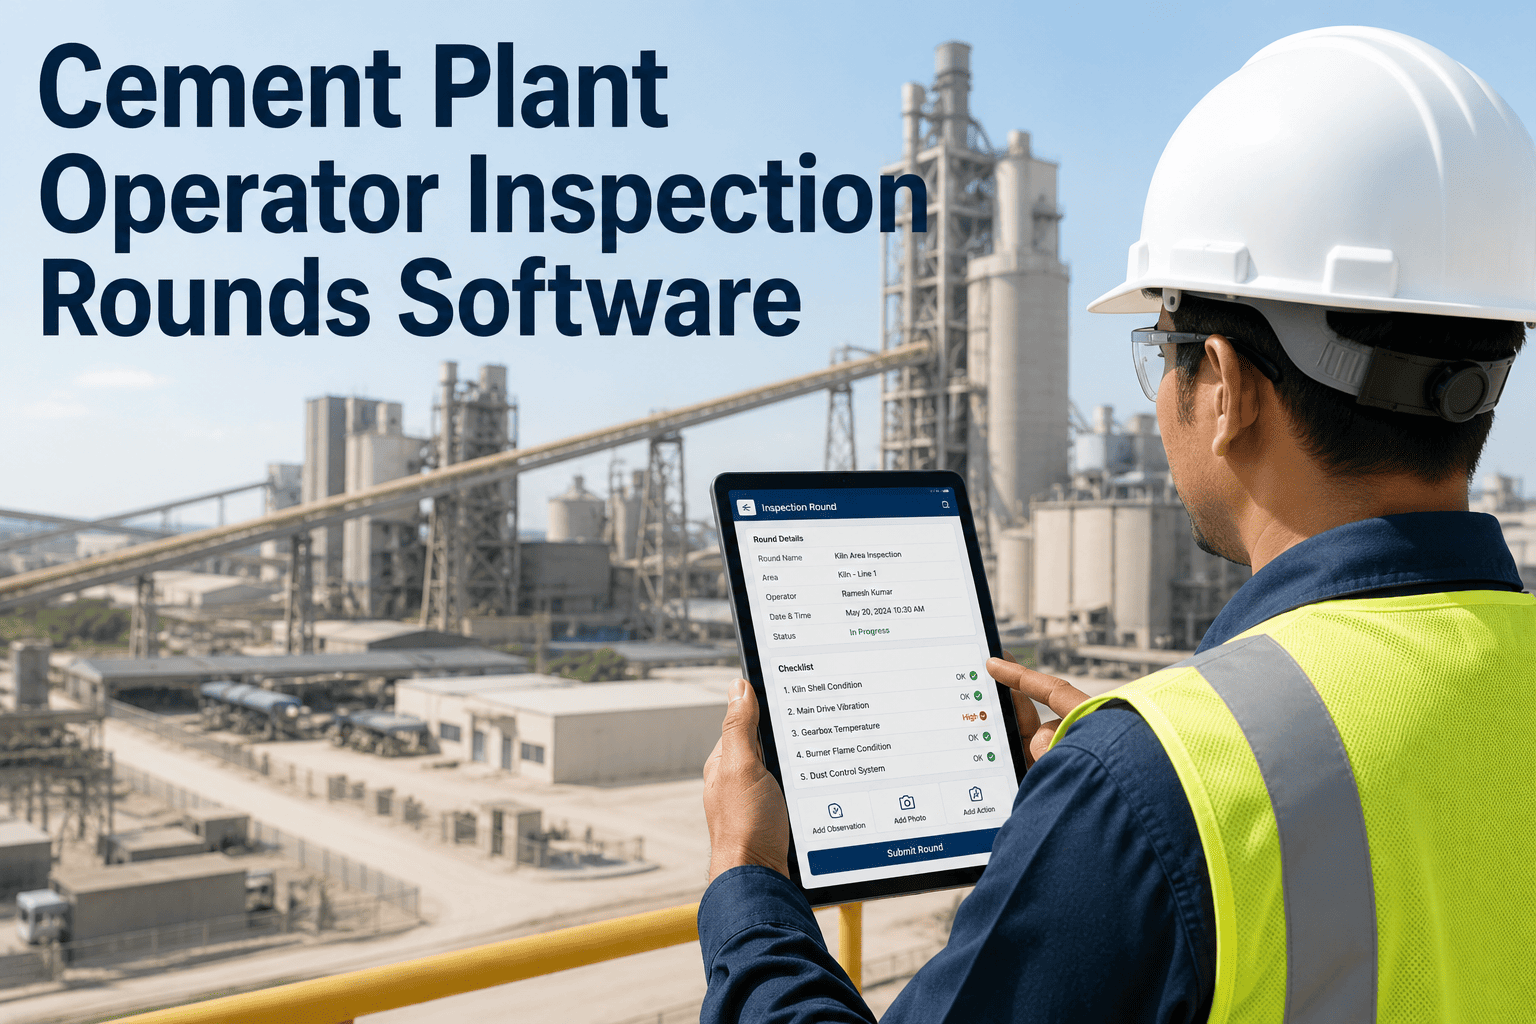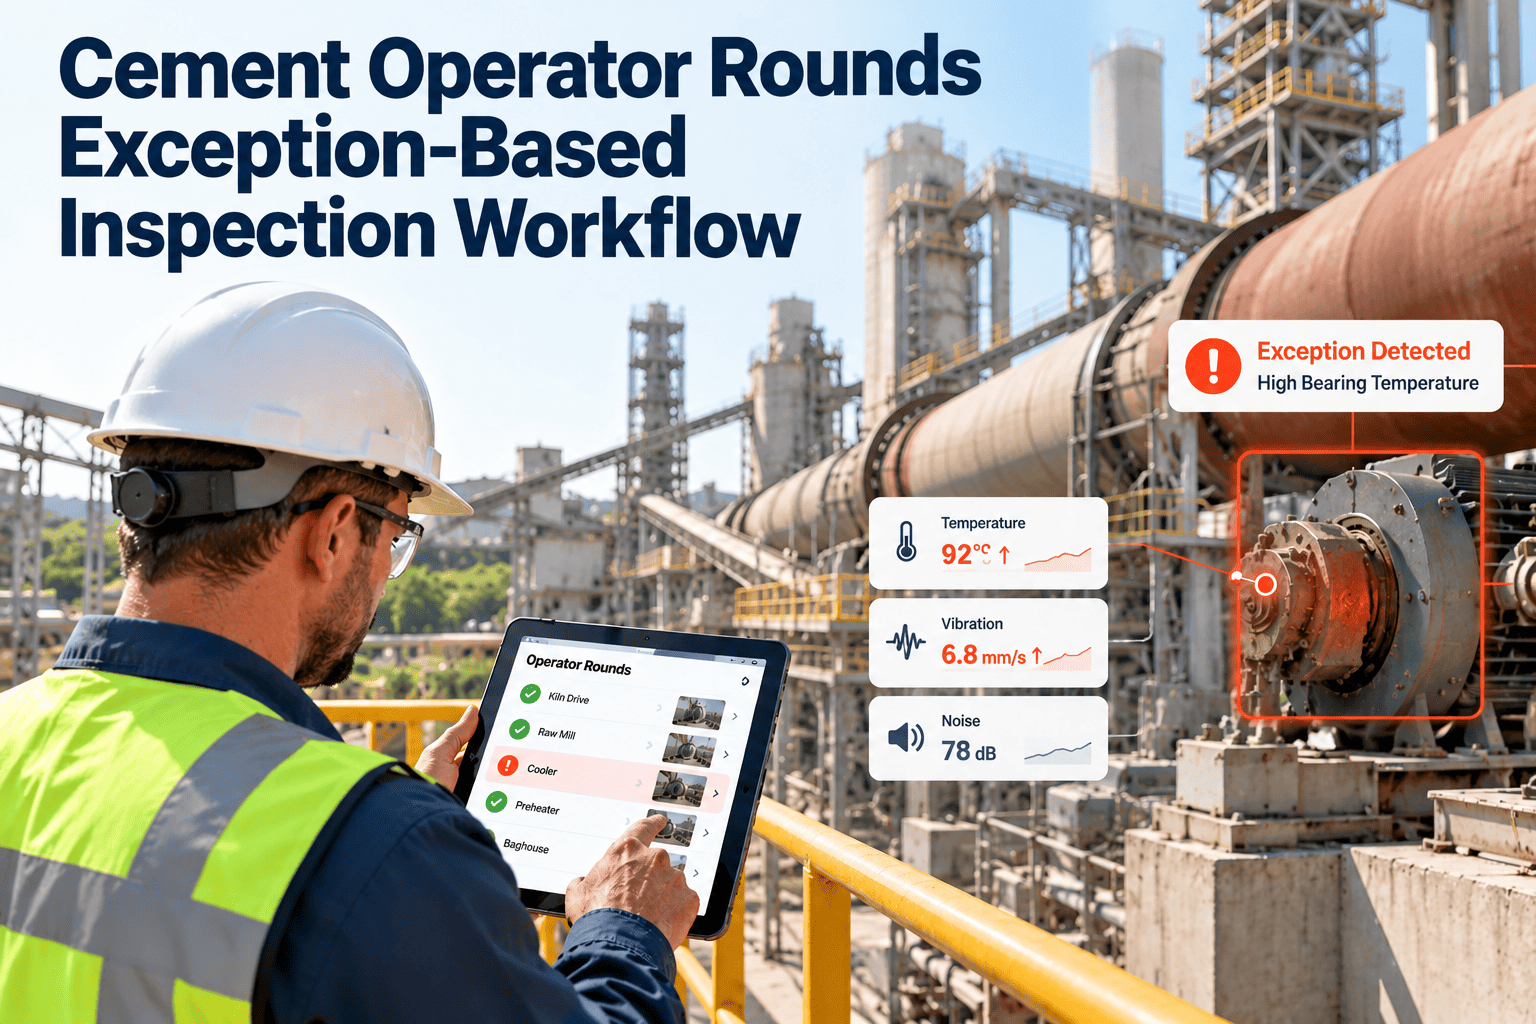
Most cement plant rounds generate far more "normal" entries than useful information. An operator ticks a hundred boxes to report that nothing has changed, and the two entries that matter sit buried in the same sheet. An exception-based inspection workflow reverses that balance. Normal conditions are confirmed quickly, abnormal ones are captured in detail, and each exception follows a defined path to a decision. Plants usually run this inside a cement plant CMMS so that findings, priorities and repairs stay connected.
Cement Operator Rounds Exception-Based Inspection Workflow
Spend operator attention where conditions change. Confirm normal fast, capture exceptions with evidence, and route each one to the right person with a clear response time.
Full-Detail Rounds Versus Exception-Based Rounds
- Every checkpoint asks for a written value or comment
- Operators spend time on readings that never change
- Reviewers scan long sheets to find the problem
- Important notes look the same as routine ones
- Normal is a single confirmation against a defined range
- Operators write detail only when something differs
- Reviewers see a short queue of real findings
- Severity and evidence accompany every exception
Start by Defining What Normal Looks Like
Pitfalls when setting limits
- Limits copied from the nameplate rather than actual operating behaviour create alarms that nobody believes.
- Limits set so wide that nothing ever triggers hide slow degradation.
- Limits that nobody reviews drift out of date after equipment upgrades or process changes.
The Exception Decision Path
Severity Tiers and Response Expectations
| Tier | Typical trigger | Who responds | Expected response |
|---|---|---|---|
| Critical | Safety hazard, active leak of hot or hazardous material, sudden drive overload | Shift supervisor and maintenance lead | Immediate action, with production informed |
| High | Readings in the action band, fast-changing trend, visible damage on a critical asset | Planner and area engineer | Same shift review, work scheduled at the earliest safe window |
| Medium | Readings in the caution band, minor leak, loose or worn component | Planner | Reviewed within the planning cycle and added to the schedule |
| Low | Cosmetic or housekeeping issue, minor noise with no trend | Area supervisor | Batched with planned work or routine housekeeping |
Make Every Exception Reach Someone Who Can Act
Define severity, owner and response time once, then let the workflow do the routing.
Why Real Exceptions Still Get Missed
Escalation and Shift Handover
Keeping alerts useful over time
- Review the ten most frequent exceptions each month and decide whether each reflects a real defect or an unsuitable limit.
- Combine related checkpoints, so one underlying problem does not create several separate reports.
- Reserve the highest severity tier for situations that really need immediate action.
- Record the reason whenever an exception is closed without work, so patterns become visible.
A Weekly Exception Review That Takes Thirty Minutes
Safety, Environmental and Compliance Considerations
- Some exceptions, such as hot surfaces without guards, dust emissions or fluid leaks, carry safety or environmental obligations beyond maintenance. Mark them so the right person is informed.
- Keep time-stamped records of the exception, the response and the verification, because incident reviews and audits ask for evidence.
- Make sure operators know when to stop and call for help instead of recording and continuing the round.
- Brief contractors and visiting technicians on how to raise an exception during their own walk-downs.
- Do not rely on a mobile alert alone for imminent danger. Critical situations should also follow the plant's emergency communication procedure.
- Check that devices and photo capture are allowed in restricted or classified areas before rollout.
What Operators Capture When They Raise an Exception
From Exception to Closure: The Life of a Finding
Questions triage should ask about every exception
- Has this asset raised the same exception before, and what was done last time?
- Is the reading moving quickly, slowly or not at all compared with the previous rounds?
- What is the consequence of failure on this asset: lost clinker output, safety exposure or minor inconvenience?
- Can the work be done while the plant runs, or does it need a stop and a planned window?
- Are the parts, skills and permits available, or does the response need lead time?
- Who needs to know, including production, quality, safety and the area supervisor?
Handling Exceptions That Do Not Need a Repair
Typical Cement Plant Exceptions and Likely Responses
| Area | Example exception | Possible cause to check | Typical first response |
|---|---|---|---|
| Kiln drive | Motor current trending upward | Gearbox wear, alignment, tyre or roller issue | Compare with history, inspect lubrication, request vibration check |
| Mill gearbox | Oil temperature rising | Cooler fouling, low oil, bearing wear | Check oil level and cooling, notify planner |
| Process fan | Bearing vibration felt stronger | Build-up on impeller, loose mounting, bearing damage | Request measurement, plan cleaning or inspection |
| Belt conveyor | Belt wandering to one side | Misaligned idlers, material build-up, damaged roller | Adjust or flag for idler inspection |
| Bag filter | Rising differential pressure | Blocked bags, cleaning system fault, moisture | Check cleaning cycle and compressed air, raise work order |
| Packing plant | Weight drift on bags | Scale calibration, spout wear, feeder fault | Recheck zero and calibration, plan repair |
Using Exception Data to Improve Maintenance
How Oxmaint Supports an Exception-Based Workflow
- Inspection templates define normal ranges, pass or fail choices and required notes per checkpoint.
- Mobile workflows let operators confirm normal quickly and capture photos and comments on exceptions.
- Failed checks can create work requests that planners triage and convert into work orders.
- Asset management shows previous exceptions and repairs on the same machine during triage.
- Scheduling and preventive maintenance help turn recurring findings into planned tasks.
- Dashboards and reports track open exceptions, response times and repeat defects by area.
- Compliance records keep time-stamped evidence of what was checked and what action followed.
Measures That Show the Workflow Is Healthy
Rollout Sequence for an Exception-Based Programme
Signs the programme is maturing
- Planners trust the queue and triage most exceptions on the same day.
- Operators describe findings in specific terms, with photos that need little follow-up.
- Repeat exceptions lead to root cause reviews and changed preventive tasks.
- Unplanned stoppages on covered assets are preceded by earlier recorded warnings, which then lead to better lead times.
Implementation Checklist
- Normal ranges for critical assets
- Severity tiers and owners
- Response times for each tier
- Required notes and photos on failure
- Automatic requests for action-band readings
- Verification step on the next round
- Weekly review of open exceptions
- Quarterly limit review with engineering
- Feedback to operators on outcomes
Frequently Asked Questions
Focus Operator Attention on What Has Changed
Run exception-based rounds in Oxmaint and turn each abnormal finding into a prioritised, tracked and verified action.